Speed Test a Local AI (LLaMA) and others
INTRO
If you want the liveliest local model right now, Meta’s LLaMA is the usual first pick: light on the machine and quick to answer. It runs on your computer, so there is no server queue and no cloud hop.
On a MacBook Air, unified memory and GPU acceleration let sentences start streaming the moment you ask. That snap is the point of running it locally. This test put the same question — what is an EV battery management system (BMS)? — to ChatGPT, Gemini, Grok, and LLaMA on this laptop, then timed the replies and asked a second question a stopwatch cannot answer: is the text ready to publish?
1. What we compared
The four systems were Gemini Flash, ChatGPT, a local LLaMA running on an M2 MacBook Air, and Grok. The prompt asked for a beginner-friendly explanation of an EV BMS. The clock started with the prompt and stopped when the full answer was on screen.
On raw speed, a light cloud model wins. For a blog post or a class handout, the better question is how much editing remains.
2. Speed results
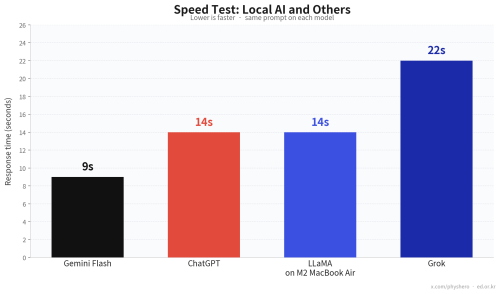
Gemini Flash finished first at 9 seconds. ChatGPT and local LLaMA tied at 14 seconds. Grok took 22 seconds. A local model matching a mid-size cloud model on the clock is interesting. The drafts below the chart show that those two 14-second runs were not equal.
Figure. Response time for the same prompt. Lower is faster.
3. Content readiness
Readiness means: can this draft go on a blog or into a class packet without a rewrite? The checks were factual accuracy, coverage of core BMS jobs, structure, language quality, and fit for a beginner.
| Model | Ready as-is? | Accuracy | Verdict |
| ChatGPT | Yes | High | Definition, sensing, charge control, balancing, SOC/SOH, thermal limits. Textbook order. |
| Grok | Almost | High | Adds protection, vehicle comms, SOH for service, and driving habits. Strip leftover markup. |
| Gemini Flash | Yes, as a short piece | High | Three-role outline is the easiest scan. Thin if you need a full explainer. |
| LLaMA (local) | No | Low | Misses the real jobs and invents false ones. Full rewrite. |
What the three cloud models all got right
Voltage, current, and temperature monitoring. Protection against overcharge, overdischarge, and overheating. Cell balancing. State of charge (SOC) and state of health (SOH) on the dash. ChatGPT, Gemini, and Grok all named those four jobs. That is the skeleton a beginner explanation cannot skip.
4. Takeaways
The same prompt does not mean the same idea of “done.” A stopwatch will not show that. This BMS test did.
- On speed: Gemini Flash (9 s), then ChatGPT and local LLaMA (14 s), then Grok (22 s).
- On copy you can use: ChatGPT and Grok lead. Gemini is enough for a short card.
- Local LLaMA matched a cloud model on the clock and still needed a full rewrite. Offline inference and publishable prose are different skills.
- If this has to become one blog post, start with ChatGPT’s clean frame and fold in Grok’s protection and driving-habit lines.
Since this test is mainly about speed, many would find LLaMA performed poorly on readiness. As a next step, I’ll follow up with a fuller English test.